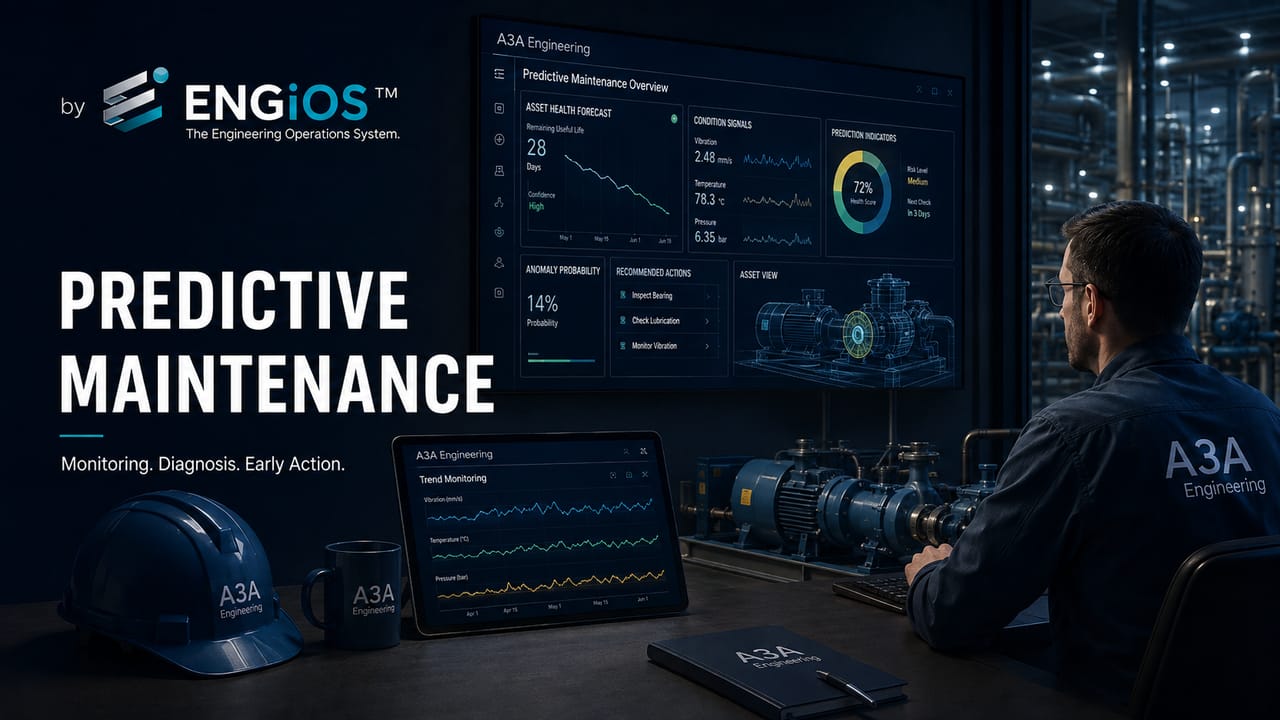
Understand predictive maintenance, condition monitoring, P-F interval, criticality, diagnostics, techniques and criteria for applying the strategy in engineering assets.
Check it out!
Predictive maintenance is a maintenance strategy based on the systematic assessment of an asset’s condition and performance to anticipate the need for intervention before a functional failure occurs. Instead of performing a task merely because a predefined time interval has elapsed, the decision is supported by actual signs of degradation, trends, measurements, inspections, and technical analysis.
In the classical terminology of ABNT NBR 5462, predictive maintenance uses systematic analysis techniques and monitoring or sampling methods to reduce unnecessary preventive interventions and decrease corrective maintenance. The contemporary asset-management approach broadens this reasoning: ABNT NBR ISO 55001:2024 treats predictive action as decision support for determining the appropriate time for maintenance, renewal, replacement, or decommissioning, relating condition, performance, risks, opportunities, and costs.
Therefore, predictive maintenance does not simply mean installing sensors or performing thermography. A program is technically consistent only when it transforms reliable data into diagnosis, criticality assessment, and engineering decisions. For some assets, the best decision will be to continue operating and monitor; for others, to bring an intervention forward; in critical situations, to develop an upgrade design, review protection systems, plan a shutdown, replace an asset, or change the maintenance strategy itself.
It is especially useful when there is a degradation mechanism that can be detected before loss of the required function and when the interval between anomaly detection and failure is long enough to analyze, plan, and execute a response consistent with the risk. When failure is essentially random, no technically correlated condition variable exists, or monitoring cost is not justified, other strategies may be more appropriate.
How predictive maintenance works in practice
The logic begins with the function the asset needs to perform and the failure modes capable of compromising that function. Only then are the parameters that can actually reveal degradation defined. Temperature, vibration, insulation resistance, partial discharge, oil quality, ultrasound, electrical current, pressure, flow, or other variables have no value by themselves: they become useful when they have a known relationship with a failure mechanism and are analyzed under actual operating conditions.
An isolated measurement is rarely sufficient. The result needs to be compared with acceptance criteria, history, trend, load condition, environment, asset characteristics, and, where applicable, manufacturer references and design requirements. This contextualization is what allows a normal process variation to be distinguished from degradation that requires investigation.
The workflow shows why prediction should be integrated with Maintenance Engineering. The ultimate objective is not to generate a measurement report, but to produce information reliable enough to decide what to do, when to do it, and with what priority.
What predictive maintenance actually predicts
The term may suggest that the technique precisely predicts the exact date of failure. In practice, this is neither always possible nor necessary. The objective is to estimate the evolution of a condition, recognize deviations, and establish a better decision window than the one available after failure.
ABNT NBR ISO 55001:2024 itself places predictive action in the context of decision-making. The process should make it possible to assess potential occurrences and impacts and determine the most appropriate time to intervene. This may mean estimating remaining life, but it may also mean recognizing that a parameter is moving away from expected behavior and that an investigation should be brought forward.
In complex facilities, the decision also depends on consequences. Two assets with the same degradation trend may receive different responses if one has redundancy and low operational impact while the other supports a critical safety, production, or business-continuity function.
Predictive, preventive, and condition-based maintenance are not the same thing
When an organization collects condition data but lacks clear criteria for turning alarms into priorities, the technology begins to generate information without governance. Maintenance Engineering structures criticality, decision criteria, responsibilities, and treatment of findings so that prediction results in verifiable actions.
The three approaches are related, but they are not synonymous. The distinction matters because a maintenance plan can combine different policies for different assets and failure modes.
| Strategy | Primary trigger | Decision basis | Typical application |
| Preventive maintenance | Time, usage, or predefined criterion | Periodicity or prescribed rule | Replacement, inspection, or intervention scheduled before failure |
| Predictive maintenance | Trend or forecast obtained through systematic analysis | Condition, behavior, and diagnostic data | Anticipate the need and timing of intervention |
| Condition-Based Maintenance (CBM) | Observed asset condition | Limits, trends, alarms, and condition assessment | Intervene when condition indicates an actual need |
| Corrective maintenance | Failure or loss of required function | Occurrence of breakdown | Restore function after failure |
A mature program does not choose a single strategy for the entire facility. The choice needs to consider required function, failure modes, detectability, criticality, safety, operational impact, lifecycle cost, and the organization’s response capability. This is why Condition-Based Maintenance and Reliability-Centered Maintenance are complementary to, rather than competitors of, predictive maintenance.
Which techniques can be used
There is no universal predictive-maintenance technology. The technique needs to be selected according to the physical phenomenon that precedes failure and the information required for the decision.
| Technique or data source | What it can reveal | Interpretation considerations |
| Thermography | Abnormal heating, thermal asymmetries, degraded connections, and apparent overloads | Load, emissivity, reflections, distance, and environmental conditions affect the reading |
| Vibration analysis | Imbalance, misalignment, looseness, bearing defects, and rotating phenomena | Requires an operating reference, measurement position, and coherent spectral analysis |
| Ultrasound | Discharges, leaks, friction, and phenomena not directly perceptible | Background noise, access, and collection technique affect the result |
| Oil and particle analysis | Contamination, wear, lubricant degradation, and internal condition | Sampling, collection point, and history are decisive for comparability |
| Electrical testing | Changes in insulation, resistance, contacts, circuits, and components | Method, instrument, test condition, and criteria need to be documented |
| Process variables | Deviations in current, temperature, pressure, flow, power, or efficiency | Process and load may explain the variation without an asset failure |
| Continuous monitoring | Temporal evolution and transient events | Large data volumes do not replace alarm architecture, context, and governance |
In electrical systems, for example, thermography can be extremely useful for identifying thermal anomalies. However, a thermal image should not automatically be treated as a final diagnosis. The finding needs to be correlated with loading, connections, design, protection, history, criticality, and operating conditions before the action is defined.
The P-F interval and inspection frequency
A useful concept for structuring predictive tasks is the interval between the point at which a potential failure can be detected and the moment when the required function is lost. This interval is often represented as P-F.
Inspection frequency needs to make it possible to detect degradation early enough to confirm the finding, analyze severity, plan resources, prepare documentation, and execute the intervention. A technically excellent inspection performed at an interval longer than the available decision window may arrive too late.
Therefore, periodicity should not simply be copied from a generic table. It needs to reflect the speed of the degradation mechanism, the detection capability of the technique, the criticality of the function, and the time required to mobilize a safe response.
Criticality and risk determine where predictive maintenance creates the most value
Continuously monitoring everything is usually economically inefficient. Predictive maintenance creates more value when the organization selects assets and failure modes for which anticipating a decision reduces meaningful exposure to production loss, downtime, safety risk, environmental impact, nonconformity, or lifecycle cost.
ABNT NBR ISO 55001:2024 requires asset management to establish risk-assessment processes and consider asset criticality in relation to objectives. This logic avoids two extremes: using sophisticated techniques on low-consequence assets or, conversely, leaving critical assets subject only to reactive maintenance without technical justification.
Criticality analysis should relate consequence, probability, function, redundancy, and recovery capability. This allows the inspection strategy to move away from a uniform schedule and reflect the organization’s actual exposure.
Data quality is part of the engineering problem
A predictive program depends on knowing exactly which asset was measured, which function it supports, its criticality, and which documents represent its actual condition. When asset registers, hierarchies, or documentation are fragmented, technical diagnosis needs to begin by structuring this information.
A predictive program can produce poor decisions even when high-precision instruments are used. This happens when context, traceability, or collection consistency are missing.
A temperature reading, for example, needs to be associated with the correct asset, measurement point, date, load condition, environment, instrument, responsible person, method, and evaluation criterion. The same applies to vibration, resistance, pressure, current, or any other variable. Without these relationships, comparing results from different periods can create artificial trends.
Data management should also preserve evidence. The Engineering Asset Management makes it possible to structure identification, hierarchy, criticality, history, and documentation so that inspections and decisions do not remain disconnected. This is consistent with ISO 55001:2024, which requires determining the necessary data and information, their attributes, units, quality, sources, and collection and integration processes.
From anomaly to technical diagnosis
An anomaly is a signal for investigation, not an automatic replacement order. Engineering needs to assess whether the phenomenon is repeatable, whether the cause lies in the asset itself or in the system, whether there is a measurement error, whether the operating condition explains the deviation, and what the consequences are of continued operation.
This diagnosis may require new measurements, physical inspection, document analysis, design review, comparison with similar assets, specific tests, or a failure analysis. When the problem is recurring, techniques such as FMEA, FMECA, and root-cause analysis may reveal that the appropriate treatment is not increasing maintenance frequency, but correcting a deficiency in design, specification, installation, operation, or process.
This distinction is central. High-level maintenance does not mean performing more tasks; it means understanding why the function is being threatened and selecting the response that creates more value over the lifecycle.
Application in electrical installations
Electrical installations offer many opportunities for predictive techniques, but they also require a systemic view. Heating at a connection, increased current, insulation degradation, or abnormal protection behavior may result from a local problem, overload, imbalance, harmonics, coordination failure, design inadequacy, or a change in the load profile.
Therefore, inspection should be aligned with installation documentation. In environments subject to Brazilian NR-10 requirements, documentation status, the Electrical Installations Record where applicable, procedures, diagrams, and records need to reflect field reality. Likewise, technical requirements for low-voltage installations, grounding, and lightning protection need to be evaluated according to the standards applicable to the case, without treating a predictive technique as a substitute for design, compliance inspection, or risk analysis.
When there is a discrepancy between field conditions and documentation, an Engineering Technical Due Diligence may be necessary before priorities are established. The result can support document updates, an upgrade plan, electrical designs, specifications, budgeting, and procurement of interventions.
When predictive maintenance identifies a problem that requires engineering design
A degradation trend does not always end in a maintenance work order. In many cases, the finding reveals a systemic cause whose solution depends on Engineering.
This is where maintenance connects with Engineering Consulting. A recurring anomaly in switchboards may require a review of load distribution or a retrofit design; availability problems may justify a redundancy study; repeated component failures may require a specification review; obsolescence may require renewal planning. Engineering’s role is to transform operational evidence into a technically justifiable decision.
Governance of services and suppliers
A large share of predictive measurements can be performed by specialized service providers. Outsourcing data collection, however, does not automatically transfer responsibility for decision quality.
The contracting organization needs to define scope, methods, assets, measurement conditions, acceptance criteria, data format, evidence, responsibilities, and the process for treating findings. ISO 55001:2024 includes specific requirements for externally provided processes, products, technologies, and services, including definition of interfaces, responsibilities, knowledge sharing, and monitoring.
This governance is especially relevant when different suppliers perform thermography, testing, maintenance, automation, or other specialties. Without integration, each report may be technically correct while the organization still lacks a consolidated view of risks and priorities.
How to structure a predictive-maintenance program
Implementation should begin with the decisions the program needs to support, not with the purchase of sensors. The sequence below is an engineering reference and should be adapted to the criticality and complexity of the facility.
- Define required functions, operational objectives, and asset-performance criteria.
- Structure the asset register, hierarchy, and minimum reliable documentation.
- Identify criticality, relevant failure modes, and degradation mechanisms.
- Select techniques capable of detecting these mechanisms with useful lead time.
- Define collection points, conditions, frequencies, criteria, baseline, and data-quality requirements.
- Establish the analysis flow, responsibilities, escalation, and anomaly-treatment process.
- Integrate findings with maintenance planning, risk analysis, engineering design, and change management.
- Measure results and continuously review criteria, frequencies, and techniques.
The Maintenance Plan is the natural place to consolidate these definitions at the operational level, while asset-management policy and plans establish decision criteria at a broader level.
How to measure whether the program is working
Performance should not be evaluated only by the number of inspections performed or the volume of alarms. Indicators need to show whether the organization is detecting meaningful degradation, making decisions with sufficient lead time, and reducing exposure to relevant failures.
Metrics such as avoided functional failures, recurrence, time between detection and decision, completion of critical actions, availability, MTBF, MTTR, downtime cost, and data quality may be useful depending on the asset type. The article on Maintenance Indicators details how to structure KPIs without confusing performed activity with engineering outcomes.
The appropriate indicator is the one that helps decision-making. An organization can increase the number of measurements and simultaneously worsen management if findings are not prioritized, treated, and converted into verifiable actions.
When to hire specialized Engineering
The need for specialized support arises when the problem exceeds the capacity of an isolated operational routine: assets without reliable registers, outdated documentation, unjustified maintenance criteria, recurring failures, untreated inspection reports, critical backlog, compliance questions, modernization, or the need to coordinate multiple suppliers.
In these situations, work may begin with an inspection, Due Diligence, existing-condition survey, document analysis, or risk assessment. Based on the diagnosis, Engineering can structure action plans, update documentation, develop designs, prepare specifications, support procurement, monitor execution, inspect services, verify evidence, and conduct testing and commissioning.
This sequence preserves the owner’s technical independence. Instead of having the solution defined exclusively by the supplier selling equipment or performing maintenance, requirements and criteria are structured from the asset’s needs and business risk — a typical application of Engineering Consulting and Owner’s Engineering.
Final considerations
Predictive maintenance is a condition-based decision discipline. Sensors, thermography, vibration, testing, and algorithms are means of observing asset behavior; value emerges when this evidence is transformed into diagnosis, risk, priority, and technically justifiable action.
The most mature approach combines reliability, asset management, documentation, planning, and governance. It also recognizes that some findings should result in maintenance, while others require design, renewal, specification, procurement, inspection, or commissioning. This integration transforms predictive maintenance from an inspection activity into an effective engineering and lifecycle-management tool.
When an anomaly indicates systemic inadequacy, obsolescence, or a risk that cannot be addressed by a localized intervention, the next step is no longer maintenance but Engineering: diagnosis, design, specification, procurement, implementation monitoring, and commissioning.
Technical references
[1] BRAZILIAN ASSOCIATION OF TECHNICAL STANDARDS. ABNT NBR 5462:1994 — Reliability and maintainability — Terminology. Available at: https://www.abntcatalogo.com.br/.
[2] BRAZILIAN ASSOCIATION OF TECHNICAL STANDARDS. ABNT NBR ISO 55001:2024 — Asset management — Management systems — Requirements. Available at: https://www.iso.org/standard/83054.html.
[3] U.S. DEPARTMENT OF ENERGY. Operations and Maintenance Best Practices: A Guide to Achieving Operational Efficiency. Available at: https://www.energy.gov/cmei/femp/articles/operations-and-maintenance-best-practices-guide-achieving-operational-efficiency.
Frequently asked questions
It is a strategy that uses systematic condition assessment, measurements, trends, and technical analysis to anticipate intervention needs before functional failure, supporting decisions about when and how to act.
Preventive maintenance is normally triggered by predefined intervals or criteria. Predictive maintenance uses information about asset condition and behavior to anticipate the need and timing of intervention.
Thermography is a technique that can be part of a predictive-maintenance program. A thermal image by itself does not constitute the entire strategy: the result needs to be contextualized, diagnosed, prioritized, and converted into an engineering decision.
No. The strategy should be selected according to function, failure mode, detectability, criticality, risk, cost, and response capability. For some assets, preventive or planned corrective maintenance may be more appropriate.
It is the conceptual window between the point when a potential failure becomes detectable and the moment functional failure occurs. It helps define inspection frequency and the lead time required for analysis and intervention.
When the finding reveals a systemic cause, design inadequacy, obsolescence, the need to change capacity, protection, redundancy, or another condition that cannot be resolved through a localized maintenance action.
Additional technical materials
Related solutions
- Electrical Safety and NR-10 Compliance: design, risks, documentation, and controls
- Field Applications, Inspection, and Technical Data Collection
- Management of Requirements, Evidence, and Acceptance Criteria
Related services
- Maintenance Engineering: strategies, reliability, plans, and indicators
- Reliability and Availability Engineering: criticality, failures, performance, and continuity
- Engineering Asset Management: asset registers, criticality, lifecycle, and performance
Main content on the topic
- Maintenance Plan: how to structure activities, frequencies, and criteria
- Maintenance Engineering: planning, reliability, backlog, and performance
- Preventive, Predictive, and Corrective Maintenance: how to define the appropriate strategy
